How should a municipality organise sensor alerts so critical events are handled without overwhelming on-call teams with false alarms?
At 06:30, the duty phone shows 41 new notifications. Thirty fill-level sensors repeat the same gateway outage. Ten monitoring points report scheduled maintenance as a fault. One final message concerns a rapidly rising water level, but the rule names no recipient. The larger alert count has given the on-call team less operational clarity.
A municipality should design each sensor alert as a binding work instruction. Every rule needs a service-relevant condition, a priority based on impact and urgency, a reachable recipient, a concrete first action, a response target and a fallback route. Readings that need no immediate action belong on a dashboard or in a planned task. Repeated events, dependent failures and known maintenance should not multiply notifications. The duty officer then receives only messages that call for action within a defined time.
Four destinations separate observation from interruption
The service department should first choose the right destination for each sensor signal. The UK Government Digital Service advises digital teams to alert only on problems that affect users, require action and persist beyond a brief fluctuation. Status information without an action belongs on a dashboard according to the GDS alert-management guidance. Municipal sensors operate in another domain, but the distinction also works for water levels, bin fill levels and indoor climate.
| Destination | Suitable condition | Municipal example |
|---|---|---|
| Log | later evidence, no current decision | one repeated radio packet |
| Dashboard | situational view without a fixed response time | soil moisture falls within its normal seasonal range |
| Task | work can wait for a planned service window | battery reaches its replacement reserve |
| Interrupting alert | a named person must act within a short period | a critical water level continues to rise after validation |
By choosing the destination, the service department stops every threshold breach from reaching the phone. An alert costs more than a data point because it interrupts work, consumes attention and needs ownership, action and closure. The department should decide from the operational consequence rather than the ease of writing a technical rule.
A municipal sensor alert is a time-bound work instruction that connects an observed condition with a named role, an executable first action, a response target and a fallback route. If one element is missing, the platform should log or display the state, or create a planned task, instead of interrupting a person.
Write the rule backwards from the required action
The UK Health and Safety Executive sets out a transferable principle for industrial alarm systems: alarms should draw attention to conditions requiring timely assessment or action, and each alarm should be useful, relevant and tied to a defined response. The HSE alarm-management principles also call for enough time to complete that response before the condition escalates.
A municipal team should therefore write the rule backwards from the work step to the reading. Its alert record contains eight fields:
- affected location or asset,
- service consequence if nobody acts,
- trigger condition and minimum duration,
- required plausibility check,
- priority and response target,
- responsible functional role and deputy,
- first safe action and runbook link,
- criterion for closure or handover.
Consider a water level of 82 centimetres. Without the site and trend, it remains a number. At a culvert with a known blockage risk, ten minutes of continued rise may trigger an inspection. A point under maintenance should produce no notification. The team also records the timezone, unit, observation time and quality status, so the recipient does not mistake an old or converted value for a new situation.
Impact and available response time set the priority
A large numerical value does not create urgency on its own. Operations should assess two axes: the likely service consequence and the time left for useful action. A small matrix gives every department the same vocabulary.
| Class | Consequence and time | Channel | Expected response |
|---|---|---|---|
| P1 | severe consequence, minutes to decide | primary on-call channel plus confirmed backup | acknowledge at once and verify the situation |
| P2 | material consequence, action within hours | alert tool or service ticket with escalation | assign within the service target |
| P3 | limited consequence, schedulable work | task queue | resolve in the normal work window |
| Information | no current action | dashboard and log | inspect during the next review |
The Google SRE Incident Management Guide recommends actionable alerts based on symptoms rather than internal causes. A municipality can apply that rule by reporting “watering route lacks current data for 18 priority young trees” instead of “webhook error 502”. Staff retain the technical cause for diagnosis, but it does not set the priority by itself.
Five filters reduce noise without hiding risk
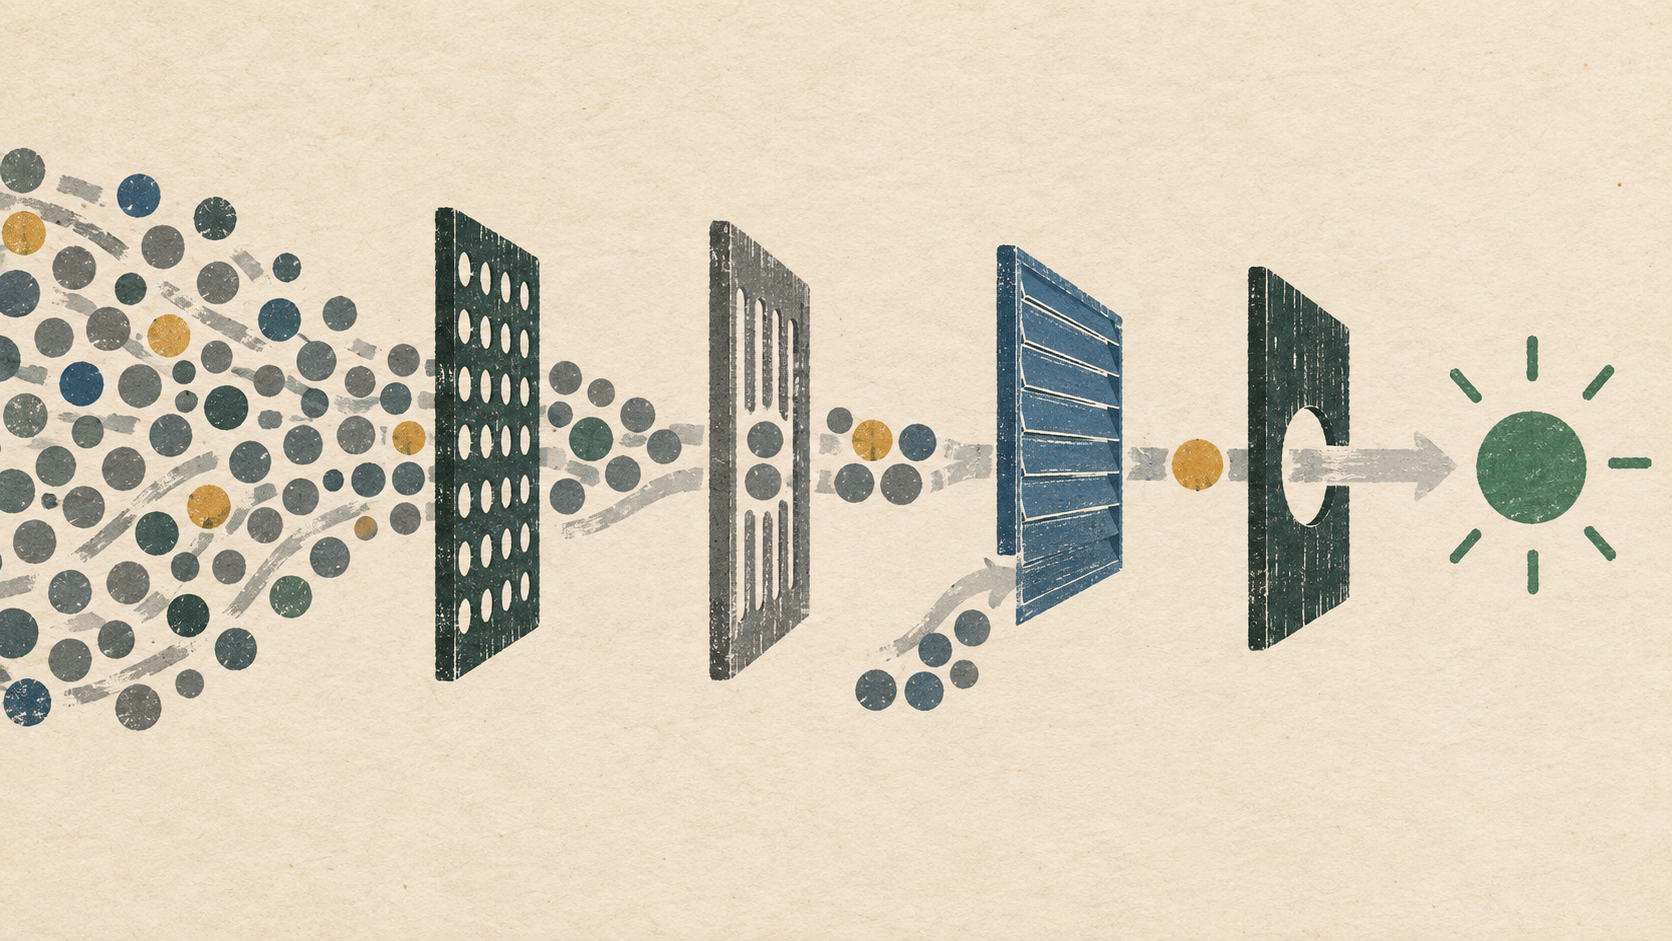
Operations should consolidate or suppress notifications only through documented rules. Five controls solve different problems:
- Minimum duration waits until a condition has persisted for the agreed period. One lost radio packet does not create an incident.
- Hysteresis uses separate thresholds for opening and closing. An alert might open above an upper value and close only below a lower one, so small measurement changes do not make it flap.
- Grouping combines matching events by cause, area or service task. One gateway outage becomes one incident with 30 affected monitoring points.
- Dependency rules hold back downstream notifications while an upstream failure is active. Staff can still see each affected point inside the incident.
- Maintenance windows pause named rules for a limited period with a reason, owner and automatic expiry.
These controls do not belong to one vendor. Prometheus Alertmanager documents deduplication, grouping, routing, time-limited silences and inhibition of dependent alerts as separate mechanisms. A municipality can use the same terms in a specification and acceptance test even when its supplier uses different technology.
Maintenance needs a firm boundary. A pause without an end time may conceal a real failure. At expiry, the system should evaluate the current state again and notify the owner if the condition remains active. P1 rules also keep an independent fallback, such as a site inspection or a second data source.
The notification carries enough context for the first safe action
The recipient should be able to take ownership without searching three systems and a spreadsheet. The message gives the location, latest observation and time, affected service task, priority and deadline, number of related events, latest known change, and a link to the runbook. It excludes credentials, cryptographic keys and unnecessary personal data.
The duty officer acknowledges ownership. If no acknowledgement arrives, the alerting tool sends the message to the deputy or control room after a defined interval. Email alone is unsuitable for a time-critical message that needs confirmation. The GDS guidance separates interrupting issues from planned tickets and warns against relying on email or chat as the only alerting tool.
Germany's Federal Office for Information Security treats reporting sources, alerting and escalation as one path in BSI Standard 200-4 on business continuity management. The standard addresses emergencies rather than routine municipal sensor operations. Its organisational lesson transfers well: define and exercise reporting, assessment, ownership and escalation before an event occurs.
Every rule needs a test alert and an expiry review
Before operational approval, the project team triggers each priority class under controlled conditions. It simulates a brief outlier, a flapping signal, a shared network outage, scheduled maintenance, an unavailable primary responder and a real escalation. The team records four intervals: condition to detection, detection to delivery, delivery to acknowledgement, and acknowledgement to first action. It also checks whether the notification closes after recovery and whether an expired maintenance window reactivates the rule.
A monthly operational review needs only a compact set of measures: interruptions per duty shift, share acknowledged within target, grouped repetitions, false alerts, missed relevant events and rules without a documented action. The team downgrades, changes or removes a rule that produces many acknowledgements but no change in service work. The service department and operations team reassess rules after seasonal changes, construction, sensor replacement and each significant incident.
An alert rule should remain active only after a test reaches the correct recipient, supplies a safe first action, proves deputy and escalation routes, and leaves evidence for reviewing false and missed events. A change to its threshold, data source, recipient or runbook starts that test again.
When urbanOS fits shared alert operations
The urbanOS Urban Data and Urban Intelligence platform for shared sensor operations is a strong fit for municipalities, utilities and large-estate operators that need to connect existing and new sensors over LoRaWAN, NB-IoT or LTE in shared dashboards and run service triggers with email actions, execution history and pause controls across several teams. It fits best where several streams, sites and owners need one common operational view and traceable handovers. The product page does not establish a complete on-call, ticketing or escalation system. The municipality and its service providers must add acknowledgement, deputy logic, independent P1 fallback routes and domain-specific rules through their operating tools. A dashboard with a scheduled daily review may be enough for a handful of low-consequence monitoring points.
Eight questions decide operational approval
The operations lead can approve a rule once the team can answer eight questions:
- Which service consequence requires action within which time?
- Why does the event justify an interruption instead of a dashboard entry or task?
- Which minimum duration, hysteresis and plausibility test apply?
- How will the system group repetitions and downstream events?
- Who acknowledges, who deputises and when does escalation begin?
- Which safe first action and fallback route are documented?
- How do maintenance windows end, and who checks reactivation?
- When did the latest test prove the complete chain?
An operations team keeps more control with a small set of clear alerts than with a continuous stream of notifications. Each interruption must lead one person to an accountable action in time.
Sources and further reading
- How to manage alertsUK Government Digital Service
- Alarm managementUK Health and Safety Executive
- Incident Management GuideGoogle Site Reliability Engineering
- AlertmanagerPrometheus Authors
- BSI Standard 200-4: Business Continuity ManagementGerman Federal Office for Information Security
- Urban data platform for municipalities and enterprisesurbanOS by dataMatters